---
title: "Strawbery Fields: Why Does Covenant-72B Look Broken?"
excerpt: "Someone on X pointed out that Covenant-72b can't count the R's in strawberry. They're right. But so were the people who laughed at GPT-4 for the same mistake two years before it started passing the bar exam. The interesting question was never whether the model fails. It's why, what that reveals about intelligence, and what happens next."
coverImage: "/assets/blog/strawberry-fields/cover.png"
category: "AI"
tags: ["Decentralized AI", "Bittensor", "Covenant AI", "Templar", "LLM", "Tokenization", "Machine Learning"]
date: "2026-03-13"
author:
name: synapz
picture: "/assets/blog/authors/profile.png"
ogImage:
url: "/assets/blog/strawberry-fields/cover.png"
---
A few days ago, a post made the rounds on X poking fun at [Covenant-72b](https://huggingface.co/1Covenant/Covenant72B). The test was simple: ask the model to count the R's in "strawberry." The model got it wrong. Screenshots were shared, laughs were had.
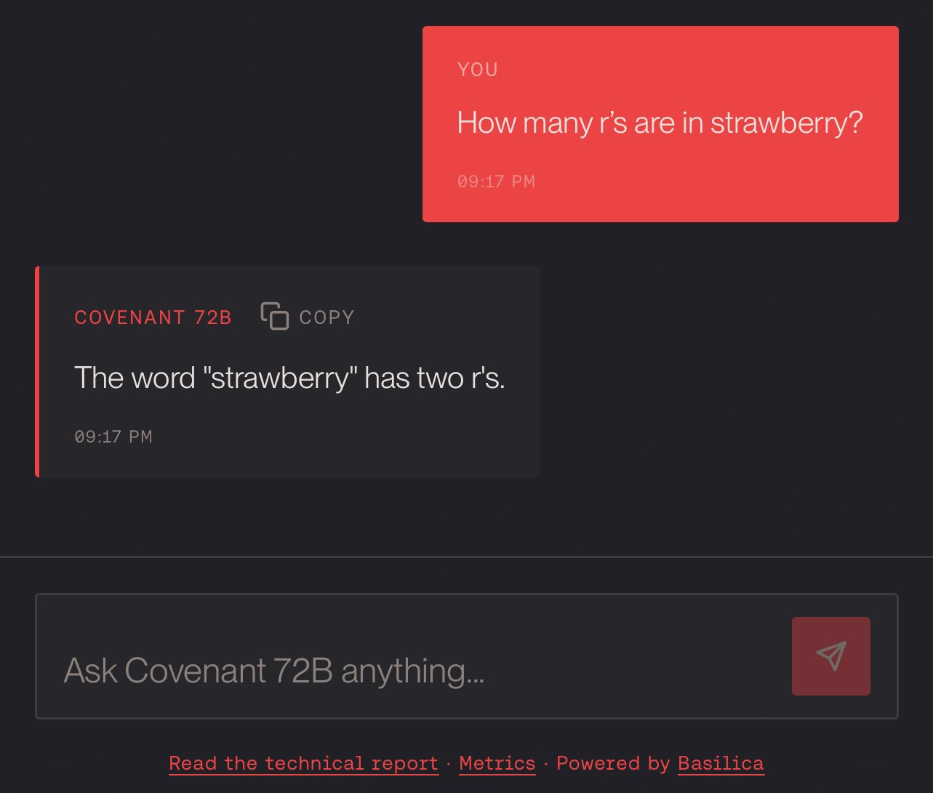
via @UnpopularDev on X
They're not wrong. Covenant-72b cannot reliably count letters in a word. Ask it to reverse a string character by character and it will stumble. These are tasks that any second-grader handles without thinking, and our model fails at them.
The interesting question is why. Two years ago, the most advanced AI systems on Earth, models built by companies with billions of dollars in compute, failed at these same tasks. OpenAI considered the problem so emblematic that when they finally built a model capable of solving it, they gave it the internal codename ["Strawberry"](https://www.newsweek.com/openai-strawberry-chat-gpt-ai-sam-altman-1925960), a project that [evolved from the mysterious Q*](https://every.to/chain-of-thought/openai-s-new-model-strawberry-explained) and eventually shipped as [o1](https://en.wikipedia.org/wiki/OpenAI_o1).
The story of why language models struggle with something this basic turns out to be one of the most revealing windows into how artificial intelligence actually works, how it differs from human cognition, and why the distance between "barely functional" and "genuinely capable" closes faster than anyone expects.
## Why the Smartest Thing in the Room Can't Count to Three
The model never sees individual letters. When you type "strawberry," what arrives is not ten characters but [tokens](https://prompt.16x.engineer/blog/why-chatgpt-cant-count-rs-in-strawberry) — chunks that the model has learned to treat as single units. A typical tokenizer splits "strawberry" into something like `st`, `raw`, `berry`. Three chunks where a human eye sees ten letters. The three R's are buried inside those chunks, invisible. Imagine trying to count the threads in a rope without untwisting it. The model sees the rope. It knows what rope is, what it is made from, how it behaves. But the individual threads are fused into the structure, and counting them requires a granularity the model does not have. [Research](https://arxiv.org/abs/2412.18626) has confirmed the problem goes deeper than token boundaries — even when repeated letters fall across different tokens, the model struggles.
It gets worse. Even if the model could see each letter, it would have to count them one at a time — and it [cannot do that](https://arxiv.org/abs/2402.12875). A language model produces every answer in a single computational breath. It is the difference between counting the red cars in a parking lot by walking row by row versus glancing at the lot for one second and guessing. The model gets the glance. You can force a workaround by asking it to "think step by step," spelling out each letter before counting, but that is the model simulating a process its architecture does not support natively.
On top of all this, language models do not run algorithms. They do not execute `"strawberry".count("r")` internally. They predict the most probable next word based on patterns in their training data. When earlier models got the strawberry question wrong, humans discussed those failures online, and that misinformation became training data for the next generation. The model is faithfully reproducing an error that is endemic in its own curriculum.
In 1988, the roboticist Hans Moravec observed that machines find "hard" problems easy and "easy" problems hard. A language model can pass the bar exam but trips over a task you could give to a six-year-old. You can solve differential equations but you cannot explain how you catch a ball. Intelligence is profoundly uneven. Every mind has capabilities that seem miraculous alongside gaps that seem absurd.
None of this is permanent. When OpenAI finally shipped a model that could count letters reliably, their [o1](https://en.wikipedia.org/wiki/OpenAI_o1) did not fix the architecture. It automated the "think step by step" workaround with hidden reasoning tokens that break problems into pieces small enough to handle sequentially. A clever hack that sidesteps the limitation without solving it. But it worked. The strawberry problem turned out to be solvable with enough engineering and enough compute. The question was never *whether* these gaps would close. It was *who* would close them, and on whose terms.
Which raises a different question: if these minds learn so differently, who gets to shape what they become?
## The Alien Student
A child learns the word "strawberry" through a collision of sensory experience. The taste, sweet and slightly tart. The dimpled red skin under small fingers. The smell of a punnet on a summer afternoon. A parent's voice saying the word while pointing. By the time a child can spell "strawberry," the word is anchored to a web of embodied memory that no amount of text could replicate.
A language model learns "strawberry" by processing statistical relationships across millions of sentences. It encounters the word in recipes, in agricultural research papers, in children's stories, in nutritional databases, in poetry. It builds an extraordinarily rich representation of how the word relates to every other word in its vocabulary. It knows more *about* strawberries than any human who has ever lived: every cultivar, every chemical compound, every cultural association in every language it was trained on. It has never tasted one. It has never held one. It has never watched one rot on a kitchen counter and felt a small pang of waste.
Both human and machine learn from patterns. Children are sensitive to the statistical regularities of language in ways that researchers are still mapping. They pick up word boundaries, grammatical structures, and phonetic rules long before anyone teaches them explicitly. In this narrow sense, a child and a language model are doing something structurally similar: extracting regularities from enormous quantities of data.
The difference is in how feedback lands. A child integrates correction through emotion, through memory, through the social weight of getting something right in front of a parent. When a parent corrects a mispronunciation, the correction arrives alongside tone of voice, facial expression, the warmth or sharpness of the moment. Reinforcement learning from human feedback, the technique used to fine-tune language models after their initial training, mirrors this loop in structure. The model produces output, a human rates it, the model adjusts. Same feedback architecture. Alien substrate. There is no embarrassment at getting something wrong, only a shift in probability weights. The outcome can look similar. The experience could not be more different.
Intelligence turns out to be stranger and more varied than our intuitions prepare us for. Counting letters is easy for humans because we have eyes, spatial processing, and a visual system that evolved over hundreds of millions of years to track individual objects in a scene. It is hard for language models because they were built to process meaning, and meaning operates at a higher level of abstraction than individual characters. A different kind of mind, with a different growth curve. And growth curves are shaped by whoever controls the training.
Right now, a handful of companies control nearly all of it. They decide what data the models learn from, what values get reinforced, what capabilities get released and at what price. The gap between a model that stumbles over "strawberry" and one that counts correctly is closed through iteration: more compute, better data, refined training. That pipeline is expensive, and the expense is the moat. Or it was, until someone proved it could be done differently.
[Covenant AI](https://www.covenant.ai) was founded to answer a question most of the industry had written off: can you train a frontier-scale model without a centralized datacenter? The team built the curriculum, approximately [1.1 trillion tokens](https://arxiv.org/abs/2603.08163) of carefully assembled training data, while a permissionless network of contributors supplied the compute. The result is Covenant-72b. Like any student with an unconventional education, it has gaps. The question is how fast those gaps close.
## Twelve Seconds at Kitty Hawk
In December 1903, Orville Wright flew a powered aircraft for twelve seconds and covered 120 feet. The major newspapers barely covered it.
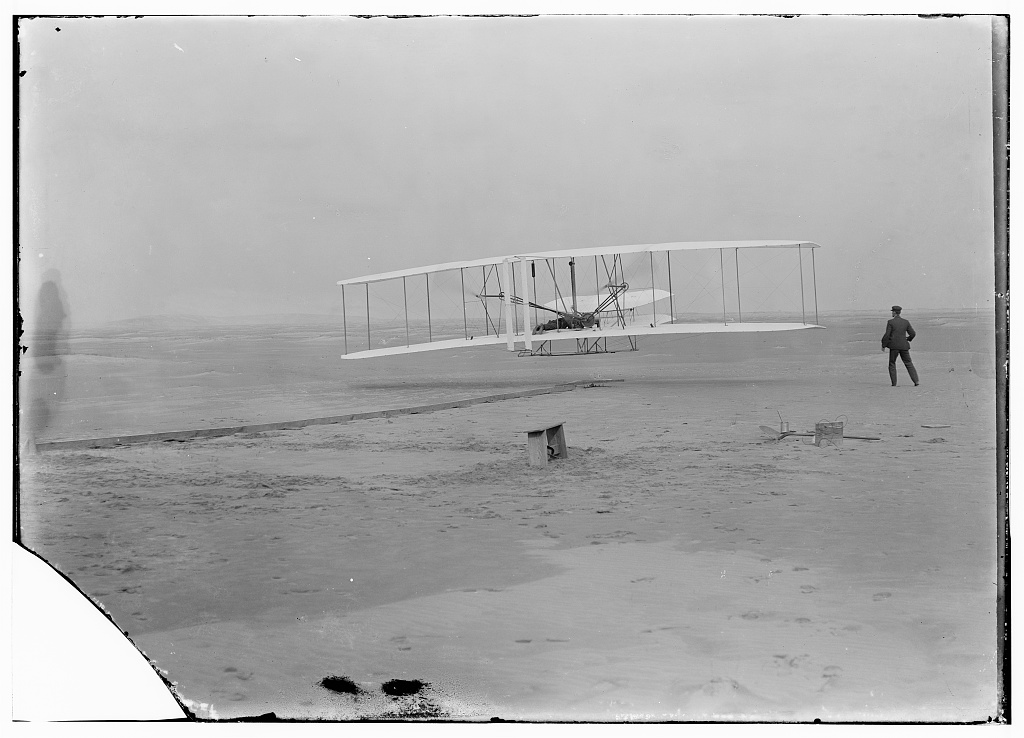
A machine that could stay airborne for less time than it takes to pour a cup of coffee did not, by any reasonable standard, look like a revolution. Sixty-six years later, human beings walked on the surface of the Moon.
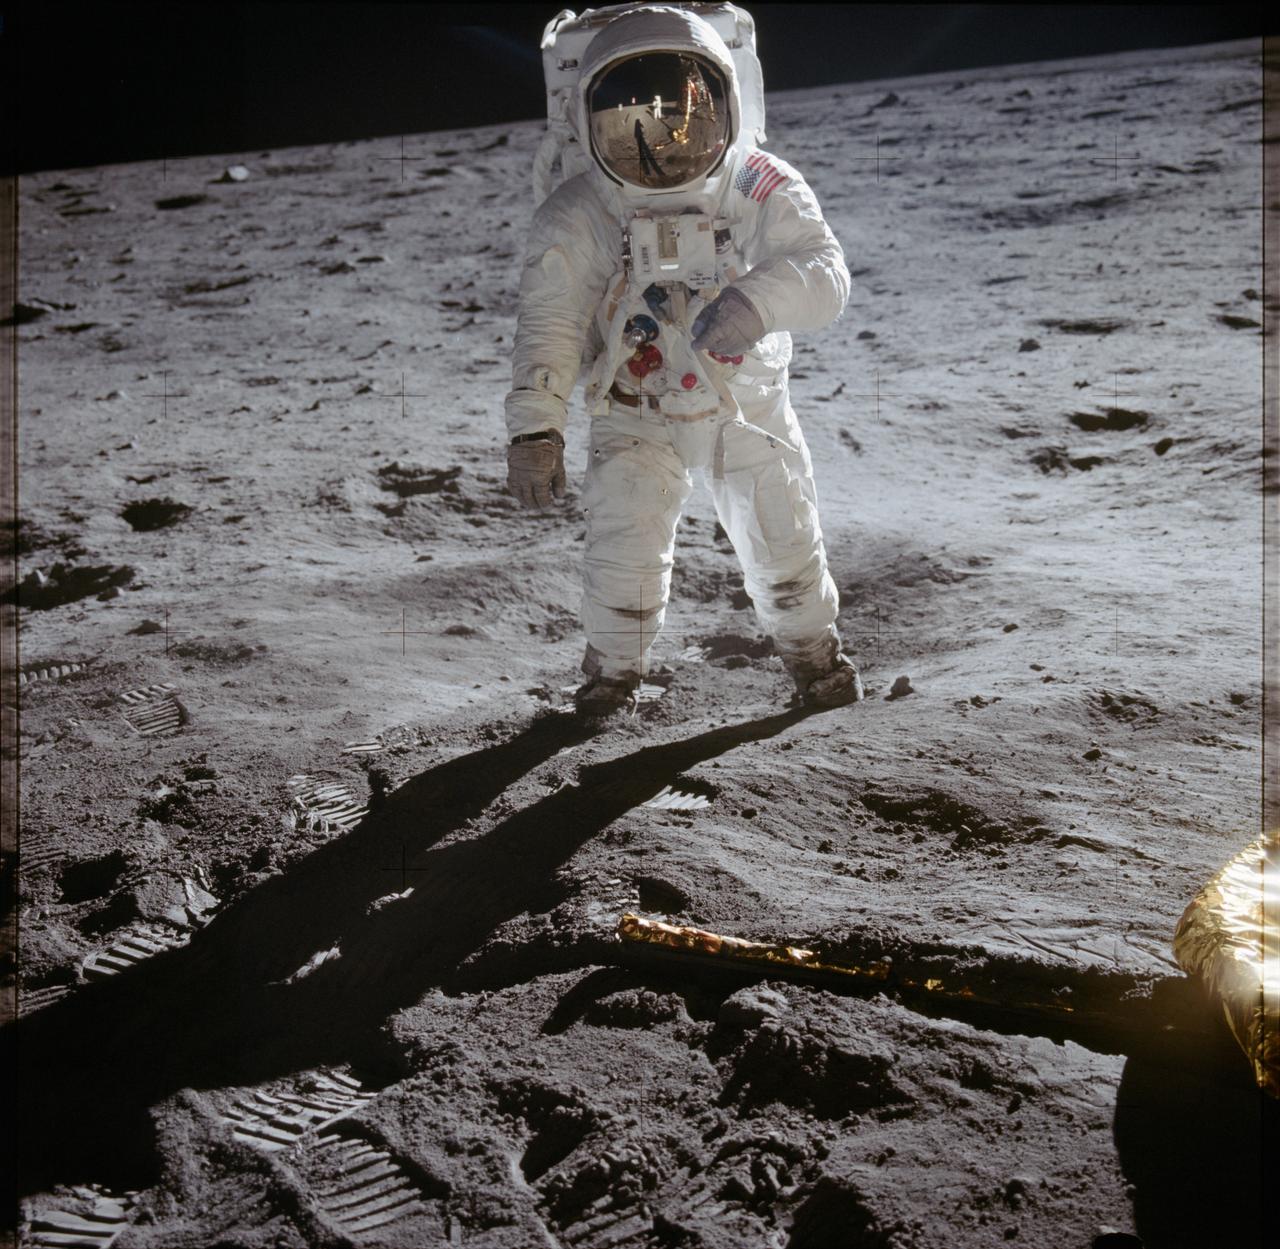
The hard part was never building a faster plane. It was proving that heavier-than-air flight was possible at all.
The pattern that followed the Wright Flyer is the same pattern that followed GPT's struggle with strawberry: the distance between embarrassing and extraordinary, closed in a fraction of the time anyone expected.
Here is what Covenant-72b proved. Seventy unique peers participated over the course of the training run on the [Bittensor](https://bittensor.com) blockchain, joining and leaving freely, their contributions scored and aggregated by the [Gauntlet](https://arxiv.org/abs/2603.08163) incentive mechanism. No central authority decided who could contribute. The model achieved a [94.5% compute utilization rate](https://arxiv.org/abs/2603.08163), with only 70 seconds of communication idle time per training round, compared to 8.3 minutes for INTELLECT-1's DiLoCo-style approach. On standard zero-shot [benchmarks](https://arxiv.org/abs/2603.08163), it is broadly competitive with centralized baselines trained at similar scale — LLM360 K2 and LLaMA-2-70B — and outperforms every other decentralized training effort. After supervised fine-tuning, Covenant-72B-Chat achieves the highest IFEval and MATH scores among all compared models in its class.
Ask it how many R's appear in a common English word and it will still get it wrong. Nobody on the team pretends otherwise. What those numbers prove is that decentralized training works at the 72-billion-parameter scale, with permissionless participation, over commodity internet connections. That is the zero-to-one. That is twelve seconds at Kitty Hawk.
The path from that point forward has already been measured. [Epoch AI](https://epoch.ai/gradient-updates/how-far-can-decentralized-training-over-the-internet-scale), an independent research organization that tracks compute trends across the AI industry, published a quantitative analysis of decentralized training scaling in December 2025. They named Covenant AI's Templar network specifically as the largest active decentralized training effort.
Since 2020, the computational scale of decentralized training projects has grown 600,000 times, at an implied rate of roughly 20x per year. Centralized frontier training, by comparison, has been growing at approximately 5x per year.
— Epoch AI, "How Far Can Decentralized Training Over the Internet Scale?" (December 2025)
We do not ask you to take our word for the growth rate. Epoch AI measured it.
The distance from "barely works" to "works well" is never measured in decades. It is measured in iterations. We [wrote recently](/posts/2026-03-07-the-900) about why the Covenant-72b moment matters as a barrier-breaking event. This post is about why the model does not work perfectly yet, and why those are two halves of the same story.
## A Tale of Two Sams
In December 2015, Sam Altman co-founded OpenAI and [wrote](https://openai.com/index/introducing-openai/): "Our goal is to advance digital intelligence in the way that is most likely to benefit humanity as a whole, unconstrained by a need to generate financial return."
Eleven years later, he stood in front of an audience of infrastructure investors at BlackRock's 2026 Infrastructure Summit and [told them](https://gizmodo.com/sam-altman-says-intelligence-will-be-a-utility-and-hes-just-the-man-to-collect-the-bills-2000732953) what the future actually looks like:
Buy it from *us*. On a meter. Follow the logic to its conclusion. If intelligence becomes the most valuable resource on Earth — and it will — then whoever controls the meter controls who gets access and who does not. Altman is not describing a future where AI lifts all boats. He is describing a tollbooth. The technology that was supposed to benefit humanity as a whole, repackaged as infrastructure for people who can pay the bill. Everyone else gets to stand on the other side of the gate and watch.
That is one Sam's vision. Here is the other's.
Sam Dare built [Covenant AI](https://www.covenant.ai) on the opposite premise: that intelligence should not have a landlord. Covenant operates three subnets on the [Bittensor](https://bittensor.com) blockchain, a decentralized network of over a hundred subnets where teams across the world are building everything from model training to inference to data pipelines, all without a central gatekeeper. The compute, the data, the training itself distributed across a permissionless network where no single company decides who participates and no one holds the meter. Covenant-72b is the first proof that decentralized training works at frontier scale. It is Prometheus stealing fire from the gods — rough, dangerous, and given freely to anyone willing to carry it.
So, yes, we shipped a model that cannot count letters. We shipped it, because the point was never to compete with frontier labs on day one. The point was to prove that the most powerful technology ever created does not have to be locked behind a corporate gate, metered and sold back to the rest of us. Covenant-72b is early and flawed, but it belongs to the network: to the researchers and engineers, to the miners running gradient computations on GPUs across the world, to the gamma token holders who believed in Sam and the Templar team before there was anything to show for it.
The next version will be better. The one after that will be better still. The curve that every breakthrough in this field has followed is the same curve we are on now, measured independently, growing four times faster than the incumbents.
One day, someone will ask a Covenant model to count letters in a word, and the model will answer correctly, and nobody will think twice about it. That is the goal. Not to impress anyone with what the model can do today, but to build toward a future where intelligence has no tollbooth, and the strawberry question is a footnote in a history that moved on to harder problems.
---
**Related Reading:**
* [The 900: Why Covenant72B Will Soon Be Ordinary](/posts/2026-03-07-the-900) — the companion piece
* [The Internet is the Datacenter](/posts/2026-01-12-the-internet-is-the-datacenter) — technical foundation
* [Covenant-72B research paper](https://arxiv.org/abs/2603.08163) — the full technical report
**Disclosure**: I work with Templar AI (formerly Covenant AI) and am directly involved in the organization's communications. For full transparency about my involvement and investments, see my [projects page](/projects). All opinions expressed are entirely my own.
Editor's note (April 2026): This post was written while I held Bittensor positions and Covenant AI operated subnets on the Bittensor network. Covenant has since left Bittensor, and I have personally divested — TAO balance zero, unstaked from every subnet. I remain with the team, since rebranded to Templar AI. The disclosure above reflects the circumstances at the time of publication. See
projects for current positions.